A&A INSIGHTS
What should happen after a free signup to an AI writing service: design the first correction, not the full draft
People sign up, sit in front of a blank composer, and leave. For the solo founder of an AI writing service, this piece rebuilds the first session around one correction the user accepted rather than characters generated, using firsthand descriptions of Lex and Chatbase.
日本語で読む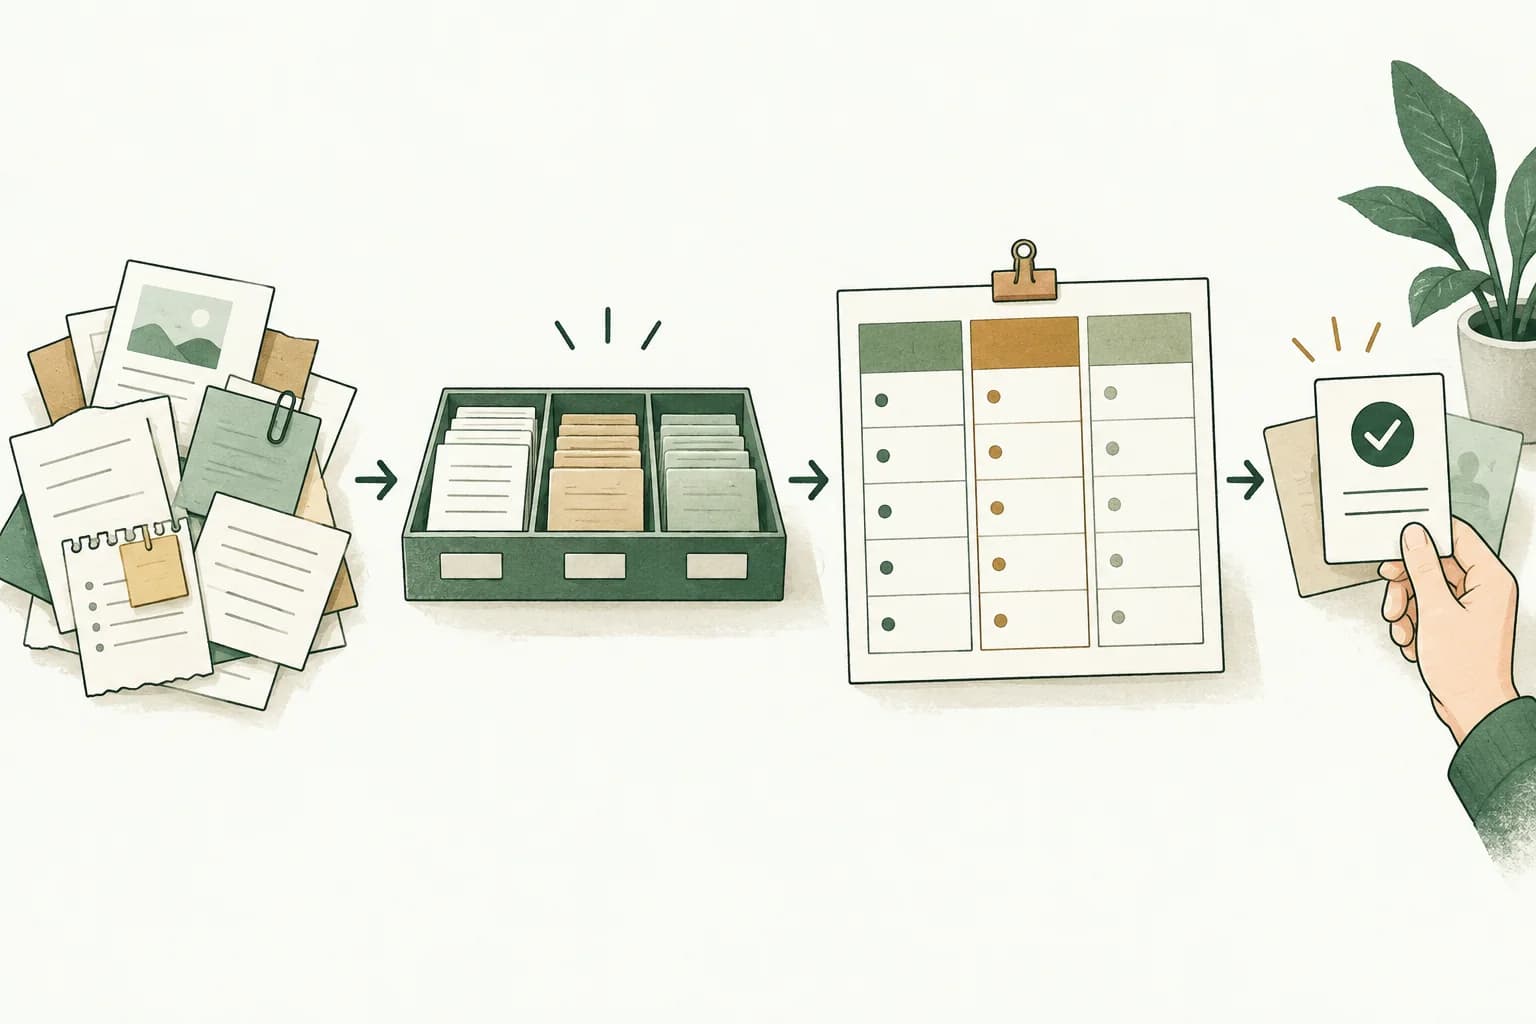
THE STARTING POINT
Signups try the product, leave the blank composer, and never return. When adding features does not bring them back, what is missing may be a definition of the first session rather than a feature. Working from two firsthand case descriptions — Lex returning remarks as comments on highlighted text, and Chatbase asking at the end whether the problem was solved — this article sets out how to decide the single move returned first, the input it acts on, and what counts as acceptance. It also covers why an accepted correction and a return visit are counted separately, and which uses this definition does not fit.
Before saying "nobody uses it": the first session was never defined
A&A perspective
Signups are climbing, but second sessions are not happening. The dashboard shows a row of records where someone opened the product, sat in front of an empty composer, and left within a minute. At this point most solo founders reach for more features: tone controls, opening-line suggestions, length adjustment. Features accumulate and return visits still do not. One reason is plain. Nobody has written down what counts as success in the first session. "Get them to try it" is not a definition of an experience. A definition means deciding three things: which input the product acts on, which single move it returns, and what has to happen before you record that value was delivered.
A&A perspective
The argument of this article is that the first-run experience of a writing-support product can be designed around one correction the user accepted, rather than around how much text was generated. There is a genuine disagreement here. The opposing position says that the moment after a free signup is exactly when you should demonstrate maximum capability, that generating a substantial piece of text in one pass is the clearest possible demonstration, and that asking users to bring their own draft only raises the barrier at the worst moment. That objection is correct for some use cases. The final section sets out exactly where.
From the sources
The case study Anthropic publishes about the writing platform Lex records the order in which the product developed. The Lex team initially focused on improving the user interface for writers, addressing concrete complaints such as cumbersome track changes. Working on the potential of generative AI came after that, according to the page. That the order runs this way, and not the reverse, is where this article starts.
What Lex returns is not a full draft but a remark on the passage you selected
From the sources
The same case study lists Lex's features concretely. First, users can tag the AI in comments for specific feedback or revisions, and the page states that this applies to text the user has highlighted. The target is not the whole document; it is the range the user chose.
From the sources
Second, document-level feedback is also offered, but the page describes its content as identifying weak arguments and suggesting improvements. It is written as work that names which of the existing arguments is weak, rather than work that adds more text. That distinction is what separates it from supplying volume.
From the sources
Third, the page states that users can create and share saved prompts for consistent feedback across teams or projects. It also lists style and brevity checks, where the model suggests ways to streamline the prose and to keep it within style guidelines.
A&A perspective
This is a feature list, but a unit of value shows through the way the features are arranged. What comes back is always a judgement about text that already exists: which part is weak, which part can be cut, which part does not meet the standard. The unit of value is not the text that was produced but one judgement passed on the user's own text. For designing a first session, that unit is far easier to observe. Generated characters can always be counted, but counting them tells you nothing about whether the user moved forward. Whether the user folded the remark into their draft is itself the record of moving forward. One caution: the case study does not say whether Lex's own post-signup screen presents these features in this order. What can be read here is the composition of the feature set, not the sequence of the onboarding flow.
| What to decide | How to write it | What happens if you cannot |
|---|---|---|
| The single first move | Narrow the advice to one thing, for example "name the weakest claim in the selected paragraph". Do not show tone, structure and summarisation at once | What counts as having experienced the product varies per user, and exits cannot be separated by cause |
| The input used | A draft close to real work that the user can supply themselves, not a sample you prepared | Success on your sample ends without telling you whether it works on their own text |
| The acceptance test | Whether the user folded the suggestion into the draft, recorded in a column separate from impressions and generated characters | Volume produced goes up while a state in which the user's text moved nowhere still gets counted as usage |
| The record of rejections | Keep the suggestions that were not applied, and the kind of passage each one addressed: a claim, structure, tone, or a factual check | There is nothing to point at as the thing to fix, so features get added and the first session becomes vaguer still |
| When not to use this unit | For uses where the user has no existing draft (producing product descriptions from structured fields, for instance), do not define the first session as an accepted correction | You end up asking people to bring text they do not have, and the only thing that rises is the barrier right after signup |
The question Chatbase placed at the end of the conversation: was it solved?
From the sources
In the case study for the customer-support product Chatbase, founder Yasser Elsaid explains the reason for the model choice this way: the responses are more conversational and give more detail, and the model asks questions at the end, trying to see if the problem was solved. Other models, by contrast, are described as going straight to the point without really conversing with the person.
From the sources
According to the same page, Chatbase built a comparison tool for customers to test different AI models side by side, and confirmed the difference on that basis. The judgement is recorded as resting on a comparison of the same inputs rather than on impression alone.
A&A perspective
A caution is needed here. Chatbase is a customer-support product, not a writing product. Carrying the design of "ask at the end whether it was solved" into the first session of a writing service is not a claim the source makes; it is a transfer made by A&A. The reason we think it is worth transferring is narrow. That closing question does not infer completion from the volume of output; it asks the other person. Translated into a writing product's first session, the design stops asking "how many words were written" and starts asking the user "was this remark usable?" And only once the user has answered does a record you can actually reason about exist on your side.
Defining the first session as one move: the input, the move, and what counts as accepted
A&A perspective
In practice three things get decided in order. First, the input: a draft close to real work that the user can supply themselves, not a sample you prepared. Something working on your sample is not evidence that it will work on their own text. Second, the move: narrow the first piece of advice down to one. Do not show tone, structure and summarisation at the same time. Third, the acceptance test: record whether the suggestion was folded into the draft, separately from impressions and from generated characters. Only when these three are filled in can an exit be separated into "value did not land" and "they left before anything was delivered at all".
Hypothetical example
Here is one hypothetical design. It is a scenario A&A constructed for explanation; it is neither the record of an existing service nor a result observed at an A&A client. Suppose a writing-support service aimed at people who write internal proposals. The screen immediately after signup does not present a list of opening lines. It presents one input field: paste a single paragraph from a proposal you already have. Against the pasted paragraph the service returns exactly one move: which claim in this paragraph is weakest, and why. Below the response sit two buttons, "apply this remark" and "do not apply". If apply is pressed, the product records what kind of passage it was: a claim, a structural point, a matter of tone, or a factual check. If do-not-apply is pressed, the same panel offers a short list of reasons. Success in the first session is defined right there. Not how many characters appeared, but whether one remark entered the draft.
A&A perspective
This definition has a secondary effect. The rejected remarks become, directly, the list of things to fix. If remarks about claims are the ones consistently rejected, perhaps the strength of a claim is not the live question in the documents you are targeting. If remarks about tone are consistently rejected, the reader you are imagining is off. Records worth looking at before adding any feature are available from the first move alone.
"Accepted the correction" and "came back the next week" are counted separately
A&A perspective
One pair must not be collapsed. That a remark was accepted in the first session, and that the person uses the product again later, are two different observations. The first shows whether value landed at that moment; the second shows whether a place was found for the product inside the person's work. Substituting one for the other leads to the wrong decision. If the first-session acceptance rate is high and return visits are absent, what needs fixing is not the first session but the positioning: which task, at what frequency, this is meant to sit inside.
From the sources
The Lex case study records a 20-30% reduction in monthly churn after fully implementing Claude. The same page also cites 25,000 signups within 24 hours of launch, and a 50% decrease in cost compared with the competitive model previously used.
A&A perspective
These figures cannot be carried over as targets. The page does not publish the denominator the percentages apply to, the periods being compared, or the definition of churn in use. On top of that, this is a customer story published by the model provider, not an independent audit. What transfers is not the numbers but the design point of keeping observations separate: recording the count of remarks accepted in a first session and the count of people who returned the following week in two different columns.
Do not mark it complete automatically: leave one click for a person to press
From the sources
The Chatbase case study also covers the part where the AI acts on real business systems. Through integrations such as Stripe, agents can handle work like checking invoices and processing refunds, with optional human oversight for sensitive operations.
From the sources
The page further states that the company is streamlining the steps where a person is involved, so that oversight can be exercised efficiently through simple one-click confirmations. It is described as a direction that reduces the number of times a person presses to one, rather than removing the person.
A&A perspective
Transposed into a writing product's first session, that single click is not only a supervision step. It is simultaneously the measurement point. Apply, or do not apply. The one press the user made is the only primary record of whether value landed. Put the other way round, a design that applies the suggestion to the draft automatically may feel smoother as an experience, but it erases the means of checking afterwards what actually happened in the first session. Smoothness and observability do not coexist here. For the first session specifically, we would choose observability.
Where this definition does not fit, and the next step
From the sources
The nature of the sources should be stated plainly. At the foot of the Lex case study an author's note records that this case study was written with help from Lex.
From the sources
The Chatbase case study likewise records that user adoption tripled since integration. It does not, however, give the date of that starting point, the number of people involved, or the definition of the increase.
A&A perspective
Both pages are therefore introductions in which the product provider and the customer both participated, not third-party verification. What should be taken from them is not the outcome figures but the composition of the features and the way completion is confirmed. With that said, here is where this article's definition does not fit. The largest case is a use where the user has no existing draft at all. For producing product descriptions from structured fields, or job postings from selected conditions, defining the first move as an accepted correction asks the user for something they do not have. In that case generation comes first and is correct, and the first-session unit changes to whether the produced text could be used as it stands. The opposing position raised at the start of this article is right here.
A&A perspective
One more caution: the phenomenon of leaving from a blank composer is not necessarily a first-session problem at all. Visitors who were never the intended audience, or a decision already made at the pricing step, show up in the same shape of record. What this article addressed is building a state in which what happened in the first session can be separated afterwards, not identifying the cause of the exits. Going further into that separation starts with splitting first-session acceptance rates by acquisition route. If the question of which single move to place first is unresolved, or if the unit of measurement itself needs to be decided again, a conversation about the definition fits better than a build.
As long as the first session is judged by characters generated, the reasons people leave cannot be separated. Return exactly one move against the user's own draft, and record whether that suggestion entered the text. With that single test in place, rejected remarks become the list of things to fix, and acceptance and return can be read as two separate figures. Where the user has no existing draft, however, this unit does not apply. If the question of which move belongs first is still open, the initial free consultation is the right place to work it out.
Sources & editorial note
Primary pages read for this article. Publication dates below belong to the sources; access dates record our research.
- Lex streamlines the writing process with Claude
Anthropic · undated case-study page; no visible publication or update date
Accessed 2026-09-24 - Chatbase helps companies deliver instant, personalized customer support with Claude
Anthropic · undated case-study page; no visible publication or update date
Accessed 2026-09-24
AI-assisted editorial production
A&A uses AI for research, writing, translation and editorial checks. Source facts, our analysis and hypothetical examples are labeled separately.
Editorial check: 2026-09-24